If Google Search Console says a blog post is not indexed, the first job is to find out whether Google cannot index it, has not yet indexed it, or has chosen not to. Those are different problems with different solutions. A noindex directive needs a settings change. A redirect may be working exactly as intended. A useful article that Google crawled but did not select requires a closer look at duplication, content value and site signals. Treating all three the same wastes time.
This guide is for bloggers managing WordPress sites, especially those with older archives, redesigned sites or posts that have lost search visibility. You will learn where to look in Search Console, how to check one URL, which fixes belong in WordPress and when to leave an excluded URL alone. The goal is not to force every URL into Google. It is to make your best, most helpful articles eligible, accessible and worth indexing.
What Indexing Actually Means
First, learn six words without the technical jargon
| Term | What it means |
|---|---|
| Crawling | Google visits a page to see what is there. |
| Indexing | Google chooses to include a page in its searchable collection. |
| Canonical URL | The preferred address when several URLs show the same or very similar content. |
| Noindex | An instruction asking search engines not to include a page in search results. |
| Redirect | An old URL automatically sends visitors to another address. |
| Sitemap | A file listing important website URLs to help search engines discover them. |
You do not need to memorize these terms. Keep this table handy while you work through the investigation.
Imagine a library. Crawling is someone looking at a book; indexing is deciding to add it to the catalog. A canonical is choosing the official edition when there are copies. A redirect is a sign pointing from an old shelf to the new one. The analogy is not exact, but it helps explain why discovering a page does not guarantee that Google will list it.
Crawling and indexing are not the same thing. Crawling means Googlebot requests a URL and examines what it can access. Indexing means Google decides to store and potentially show a version of that content in search. Ranking is a separate step: an indexed article may still receive few impressions if it does not match what people search for or if competing pages answer the question better.
A URL Inspection result is a snapshot of Google's knowledge, not a promise about future performance. Search Console reporting can lag behind changes on your site. A successful live test shows what Google can access now; it does not prove the URL has been indexed. Keep that distinction in mind throughout the investigation.
Step 1: Decide Which URLs Are Worth Investigating
Before you start: what you need
Set aside 20 to 30 minutes for your first check. You need access to your WordPress dashboard, access to Google Search Console for your website, and the web address of one important public blog post. Open a notes document so you can write down what you see. If you do not have Search Console set up, visit Google Search Console and follow Google's instructions to add and verify your website. Verification may require help from your hosting provider or whoever manages your domain. Do not change DNS settings by guessing.
For your first attempt, pick a published article that you can open without logging in. Avoid a private lesson, shop checkout page or old URL that you know redirects. This makes the investigation simpler and reduces the risk of changing something that was intentionally hidden.
Who should audit indexing? Bloggers who have redesigned a site, changed domains, installed SEO or membership plugins, merged posts, or noticed important tutorials missing from search. Start with valuable public pages rather than private course lessons, search results or tracking URLs. Make a spreadsheet recording the preferred URL, indexing reason, last check, intended canonical, importance and next action. Compare a handful of representative URLs before making a site-wide change.
Start with the pages that serve readers and your business. A complete tutorial, a useful resource page, a strong article that supports a book or course, and a well-maintained evergreen guide deserve attention. A duplicate parameter URL, an obsolete attachment page or an intentionally redirected address usually does not.
Create a small working sheet with the URL, page type, current indexing reason, intended canonical URL, business importance, date checked and next action. Investigate five to ten representative URLs first, rather than making a site-wide change based on one alarming total. If an exclusion category contains hundreds of URLs, sample both valuable articles and low-value utility URLs before deciding what the pattern means.
Step 2: Read the Page Indexing Reasons Correctly
A beginner's quick-reference table
| What Google says | In everyday language | First thing to do |
|---|---|---|
| Discovered - currently not indexed | Google knows the address but has not visited it yet. | Check that the article is published, linked from your site and included in the appropriate sitemap. |
| Crawled - currently not indexed | Google visited but did not add it to search. | Compare the article with similar pages and check whether it provides a distinct, useful answer. |
| Excluded by noindex | A setting asks Google not to list the page. | Check whether the exclusion is intentional before changing WordPress or Yoast settings. |
| Alternate page with proper canonical | Google recognizes another address as the main copy. | Open the preferred address and make sure it is the right page. |
| Page with redirect | The old address sends visitors somewhere else. | Follow the redirect and verify that the destination is correct. |
| Server error | Google had trouble getting the page from the website. | Open the page yourself and contact your host if the problem continues. |
Important: This table gives you a safe starting point, not a guaranteed diagnosis. Do not delete pages or change technical settings based only on the label.
Other reasons you may encounter: A 404 means the resource was not found; decide whether it should be restored, redirected to a genuinely relevant replacement or left missing. A soft 404 can mean a page returns a success status but looks empty or unhelpful. Server errors call for hosting and availability checks. A duplicate without a user-selected canonical calls for comparing versions and choosing a preferred URL. These are not interchangeable fixes. Avoid redirecting every missing URL to the homepage.
Discovered - currently not indexed: Google knows the URL exists but has not crawled it. Check whether the page is linked from relevant pages, appears in the sitemap, and loads reliably. A recently published or low-priority page may simply need time. Do not assume a technical block without evidence.
Crawled - currently not indexed: Google has fetched the URL but has not indexed it. Compare the article with similar pages on your own site, check whether the main content is substantial and distinctive, and inspect canonical signals. This label alone does not establish a manual action, spam penalty or specific quality defect.
Excluded by noindex: A robots meta tag or HTTP header tells search engines not to index the URL. If this is an important public article, check WordPress visibility settings and the Yoast advanced indexing control. If it is a private, thank-you or internal utility page, the exclusion may be correct.
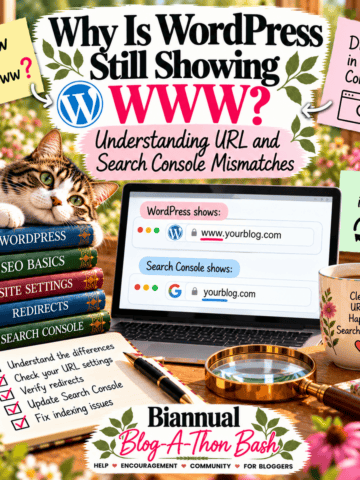
Alternate page with proper canonical: Google recognizes another URL as the preferred version. Verify that the preferred version is the one you want, particularly after changes between www and non-www, HTTP and HTTPS, or category and post URLs. Do not try to index every alternate.
Duplicate, Google chose different canonical than user: Your declared canonical and Google's selected canonical differ. Inspect both pages, compare their actual content, check redirects and internal links, and determine which URL should represent the material. A canonical tag is a strong hint, not an absolute command.
Page with redirect: The original address points elsewhere. Confirm the destination is correct and usable, then update important internal links to the destination. You generally want the destination indexed, not the retired address.
Blocked by robots.txt, server error or soft 404: These require different investigations. A robots.txt disallow can prevent crawling; a server error suggests availability trouble; a soft 404 can mean a page appears missing or has too little useful content despite returning a success response. Verify the actual response and page behavior before changing settings.
Step 3: Inspect One URL in Google Search Console
Follow these clicks for your first inspection
- Open Google Search Console and sign in with the Google account that has access to your website.
- Use the property selector near the top to choose the correct website. If you see several versions, choose the property that covers the article address you intend to inspect.
- Copy the complete URL of your published article, beginning with https://.
- Paste it into the inspection field at the top of Search Console and wait for the report.
- Read the main indexing verdict. Write down the exact message instead of guessing what it means.
- Expand the page indexing details if available. Look for the indexing permission and the Google-selected canonical.
- Select Test Live URL to check the current page. Wait for the test and note whether it says the page is available to Google.
- Do not press Request Indexing until you have decided whether a problem actually needs fixing.
If the interface looks a little different, look for the same features by name. Google sometimes changes its menus. The key is to inspect one exact URL, compare Google's stored information with the live result and write down the difference.
What to record: the exact inspected address, Google's verdict, last crawl when available, crawl permission, page fetch, indexing permission, user-declared canonical and Google-selected canonical. Then run the live test. A live test showing the corrected page does not mean Google's index has updated. It shows the current version is accessible. If you recently changed from www to non-www or HTTP to HTTPS, inspect the preferred destination, not just the retired URL. For an example, see our guide to WordPress www and non-www Search Console mismatches.
Open the correct Search Console property and paste the exact preferred article URL into URL Inspection. Record whether Google reports the URL as indexed, the last crawl if available, the page-fetch result, whether indexing is allowed, the user-declared canonical and Google's selected canonical. If Google shows a different canonical, open and inspect that address too.
Click Test Live URL to see whether Google can access the current page. The live result may differ from the indexed report because you have edited the site since Google's last crawl. If the live test reports an access or indexing problem, resolve that before requesting indexing. Save a screenshot or short note so you can compare after the repair.
Step 4: Check the WordPress Settings That Can Block Indexing
Beginner walkthrough: check without changing anything
- Sign in to your WordPress dashboard.
- Open Posts → All Posts, find the article and confirm its status is Published.
- Open the article in the editor. Find the Yoast SEO panel or sidebar. In its advanced indexing settings, look for the control that determines whether search engines may show the post in results. The exact wording and location can vary by Yoast version.
- For a public article you want indexed, the intended setting is to allow search engines to show it. If the setting says no and you are unsure why, write it down before making a change.
- Separately, visit Settings → Reading and check whether WordPress is discouraging search engines from indexing the entire site. Do not toggle it casually, especially if you manage staging or private sites.
- Return to the public article and verify that it opens in a private browser window without requiring a login.
If you find a surprising setting, change only the specific item you understand, save it and run a new live URL test. If a plugin, server header or membership rule appears involved, stop and ask for help rather than editing code. A green indicator in Yoast's content analysis does not mean Google has indexed the page.
Where to look: Settings → Reading for site-wide search visibility, the post's publication and visibility status, Yoast's advanced indexing controls, and any membership plugin that restricts access. Check the rendered HTML, not only the editor. Robots.txt crawling restrictions, robots noindex directives and canonical hints do different jobs. Blocking Googlebot from crawling a page can prevent it from seeing a noindex directive, so do not treat these settings as interchangeable. Never expose a paid lesson just to remove an exclusion warning.
In WordPress, check Settings → Reading for the option that discourages search engines from indexing the site. It is intended for sites that should not appear in search; it should not be enabled accidentally on a public blog. Then open the affected post in the editor and check its Yoast SEO advanced settings. Make sure the article is allowed to appear in search results if it is intended to be public.
Look for a robots meta tag in the rendered HTML, such as <meta name="robots" content="noindex">. A page may also send an X-Robots-Tag HTTP header, which cannot be confirmed merely by looking at the editor. Membership restrictions, password protection and certain staging configurations can also make content unavailable. Do not remove protections from paid or private material simply to satisfy Search Console.
Step 5: Check Canonicals, Redirects and Sitemaps
What a correct canonical looks like
Suppose your article is at https://example.com/growing-tomatoes/. If that is the preferred public address, its canonical normally points to that same address. If the canonical points to a different article, investigate why before changing it. A different canonical may be intentional when a page is a duplicate. For a beginner, the safest approach is to compare the preferred URL displayed in Search Console with the actual address of the article and note any mismatch.
You can also open the public article, choose your browser\'s View Page Source option and search the source for rel="canonical". If that feels too technical, use the canonical information shown in Search Console and ask for help if it is unexpected. Do not edit theme files or database records to fix a canonical.
Where to find a sitemap
Many Yoast installations provide a sitemap index at https://yourdomain.com/sitemap_index.xml, although the exact setup can vary. Open it and look for a post sitemap. Being listed helps discovery but does not guarantee indexing. If the article is intentionally private or noindexed, it may correctly be absent.
How to investigate a moved post: follow the old URL and record each redirect until you reach the destination. Check that the final page works, its canonical matches the preferred address and your sitemap and internal links point there directly. After a www or HTTPS change, many excluded old URLs may be entirely expected. A sitemap helps Google discover preferred pages but cannot override a noindex directive or force indexing. If two articles are substantially alike, consider improving one and consolidating the other instead of sending conflicting canonical signals.
A canonical URL identifies the preferred version of substantially similar content. Open the article's rendered source and find its canonical link. Compare that address with the URL you want readers to visit. Check whether the page redirects, whether navigation and internal links point to a different version, and whether the preferred page is represented in the XML sitemap.
Yoast normally generates XML sitemaps, but a sitemap is a discovery aid, not a guarantee of indexing. A URL omitted because it is intentionally noindexed may be behaving correctly. Conversely, a URL included in a sitemap can still be excluded by Google. Fix contradictory signals instead of repeatedly resubmitting the sitemap.
For more background, explore my Google tools for bloggers and beginner SEO tips. If several articles overlap, my guide to quarterly content clusters can help you organize related topics more deliberately.
Step 6: Check Whether the Article Deserves Its Own Search Result
Ask what question the page answers and what a visitor can do after reading it. Does the article include accurate instructions, real examples, troubleshooting, photographs or first-hand observations? Does it cover the important steps without burying them under filler? If two posts answer essentially the same question, decide whether one should be expanded and the other redirected or given a genuinely distinct purpose.
For an older gardening or blogging tutorial, inspect every recommendation, screenshot and product reference. Replace outdated steps, explain what changed, add examples from your experience and link to supporting articles where readers need more detail. Do not change the publication date merely to create an appearance of freshness. A meaningful update should be useful even if Google never rewards it.
Step 7: Strengthen Internal Links Without Creating Clutter
Find two or three relevant, accessible pages on your own site that can naturally point to the article. A blogging-basics hub might link to a Search Console tutorial; an article about refreshing old posts might link to this indexing checklist. Use anchor text that tells readers what they will find, not a vague 'click here.'
Also check the affected article's outgoing links. Replace links to unpublished drafts, outdated redirects or unrelated pages. Internal linking helps people navigate and can help crawlers discover pages, but adding dozens of arbitrary links is not a substitute for useful content.
Step 8: Request Indexing and Monitor the Right Results
Use a simple follow-up log
| Date | What I checked or changed | What happened |
|---|---|---|
| Day 1 | Inspected the exact URL and ran the live test. | Recorded the indexing reason and canonical. |
| After repair | Corrected a confirmed problem and tested again. | Recorded whether the live page is accessible. |
| Later follow-up | Revisited URL Inspection and Performance. | Compared crawl status, indexing, impressions and clicks. |
There is no universal day on which Google must index the article. A new live test is useful for confirming your fix; it does not force Google to recrawl or include the URL. When a page remains excluded, return to the original evidence instead of clicking Request Indexing over and over.
When to request indexing: after you have corrected the actual issue and verified the current page is accessible and indexable. Record the change and the request date. Recheck the URL later for crawl and indexing status, then examine impressions and clicks if it becomes indexed. A page that is indexed but receives no impressions needs a different investigation from one that Google has not selected. Do not keep submitting unchanged URLs or assume an indexing request guarantees search traffic.
Once the live page is accessible, indexable, canonicalized appropriately and meaningfully improved, return to URL Inspection and select Request Indexing if available. This asks Google to reconsider the URL. It does not force a crawl, indexing or higher rankings. Avoid repeatedly requesting indexing for an unchanged page.
Record the date of your repair, then check the same URL later. Look for changes in indexing status and, if the page becomes eligible for search, impressions and clicks in Search Console's Performance report. Changes may take days, weeks or longer, and some pages may never be selected. A successful cleanup can also leave many intentional exclusions in the Page indexing report.
A Realistic Example: An Older Tutorial Missing From Search
Imagine an older article about preserving apples that appears under 'Crawled - currently not indexed.' First confirm that the preferred URL loads and is not noindexed. Compare it with other apple-preservation articles on the same site. If the content overlaps heavily, decide which page should answer the main question. If the article is distinct but incomplete, improve the instructions, add clear storage distinctions, update photographs and connect it to relevant food-preservation resources.
After saving, inspect the live URL and record the repair. You can request indexing, but you cannot conclude the changes worked until Google's later reports support that conclusion. This example is a troubleshooting model, not a claim that any particular Experimental Homesteader URL has recovered.
When an Excluded URL Should Stay Excluded
Do not try to reverse every exclusion. A redirected old address should usually remain out of the index. A duplicate tracking URL does not need its own result. A private course page, account page or thank-you screen may deliberately be noindexed. The useful question is whether the preferred public page can be discovered and indexed, not whether the report contains zero excluded URLs.
Likewise, deleting a post simply because Search Console lists it as excluded can remove useful material and break existing links. Decide whether to update, consolidate, redirect, leave in place or retire each page based on what it does for readers and whether another page already serves that purpose.
Frequently Asked Questions About Google Indexing
Does 'Crawled - currently not indexed' mean Google penalized my blog? No. It is a reporting status, not a diagnosis of a manual action. Inspect the URL and the surrounding site before drawing conclusions.
Should I submit every excluded URL for indexing? No. Focus on important public canonical pages after fixing any real problem. Many exclusions are expected.
Can Yoast make Google index my post? Yoast can help configure indexability, canonical tags, sitemaps and metadata, but Google makes its own indexing decisions.
Will adding more words solve the problem? Not by itself. Add information that helps the reader complete a task or understand the topic. Repetition and filler do not make a page more useful.
How soon will Google notice my changes? A live test can show the current page immediately, but recrawling, indexing and performance changes may take longer. There is no guaranteed deadline.
A Practical Next Step
Your first indexing investigation checklist
- Choose one valuable, published, public article.
- Open the correct website in Google Search Console.
- Inspect the exact article URL and record the result.
- Run Test Live URL and compare the two results.
- Check the article's WordPress publication status and Yoast indexing setting.
- Verify that the preferred address and canonical make sense.
- Check that the article is useful, current and linked from a relevant published page.
- Fix only a problem you have confirmed.
- Request indexing if appropriate, then record the date and follow up later.
Stop and get help if the next step involves DNS, robots.txt, server headers, widespread redirects, database changes or removing membership protection. You can learn a great deal from the inspection without risking your website. Completing one careful investigation is a real accomplishment even when Google has not yet indexed the page.
Choose one important article that Search Console says is excluded. Write down the exact reason, inspect the preferred URL, check the live page and decide whether the issue is technical, duplication-related or editorial. Fix the underlying cause before requesting indexing. Then move to the next representative URL instead of changing hundreds of posts at once.
If you want to compare notes with other bloggers, bring the exclusion reason and one public article URL to the Building Better Blogs membership. A careful investigation of one real example teaches you more than chasing a dashboard number.
Leave a Reply